 OHDSI GIS
 OHDSI GIS
WG
Exercise 2: The Gaia pipeline
Goal
Run the Gaia ingestion and spatial-temporal linkage, check the result against the answer key, then trace one derived exposure row back to its source and explain it.
The artifact you are tracing is: raw dataset → source
geometry/attribute tables → location interval → derived exposure
row. gaiaDocker orchestrates the stack,
gaiaDB/PostGIS stores and transforms the data, and the
catalog metadata from Exercise 1 drives retrieval. In a real deployment,
identifiable addresses never leave the data custodian’s boundary:
geocoding and patient-level linkage happen locally, behind that
boundary. Here the locations are synthetic points inside real counties,
so you can follow the whole chain.
You start with the synthetic persons and their residence history but
no exposure data. The EXTERNAL_EXPOSURE
table is empty; producing it is this exercise.
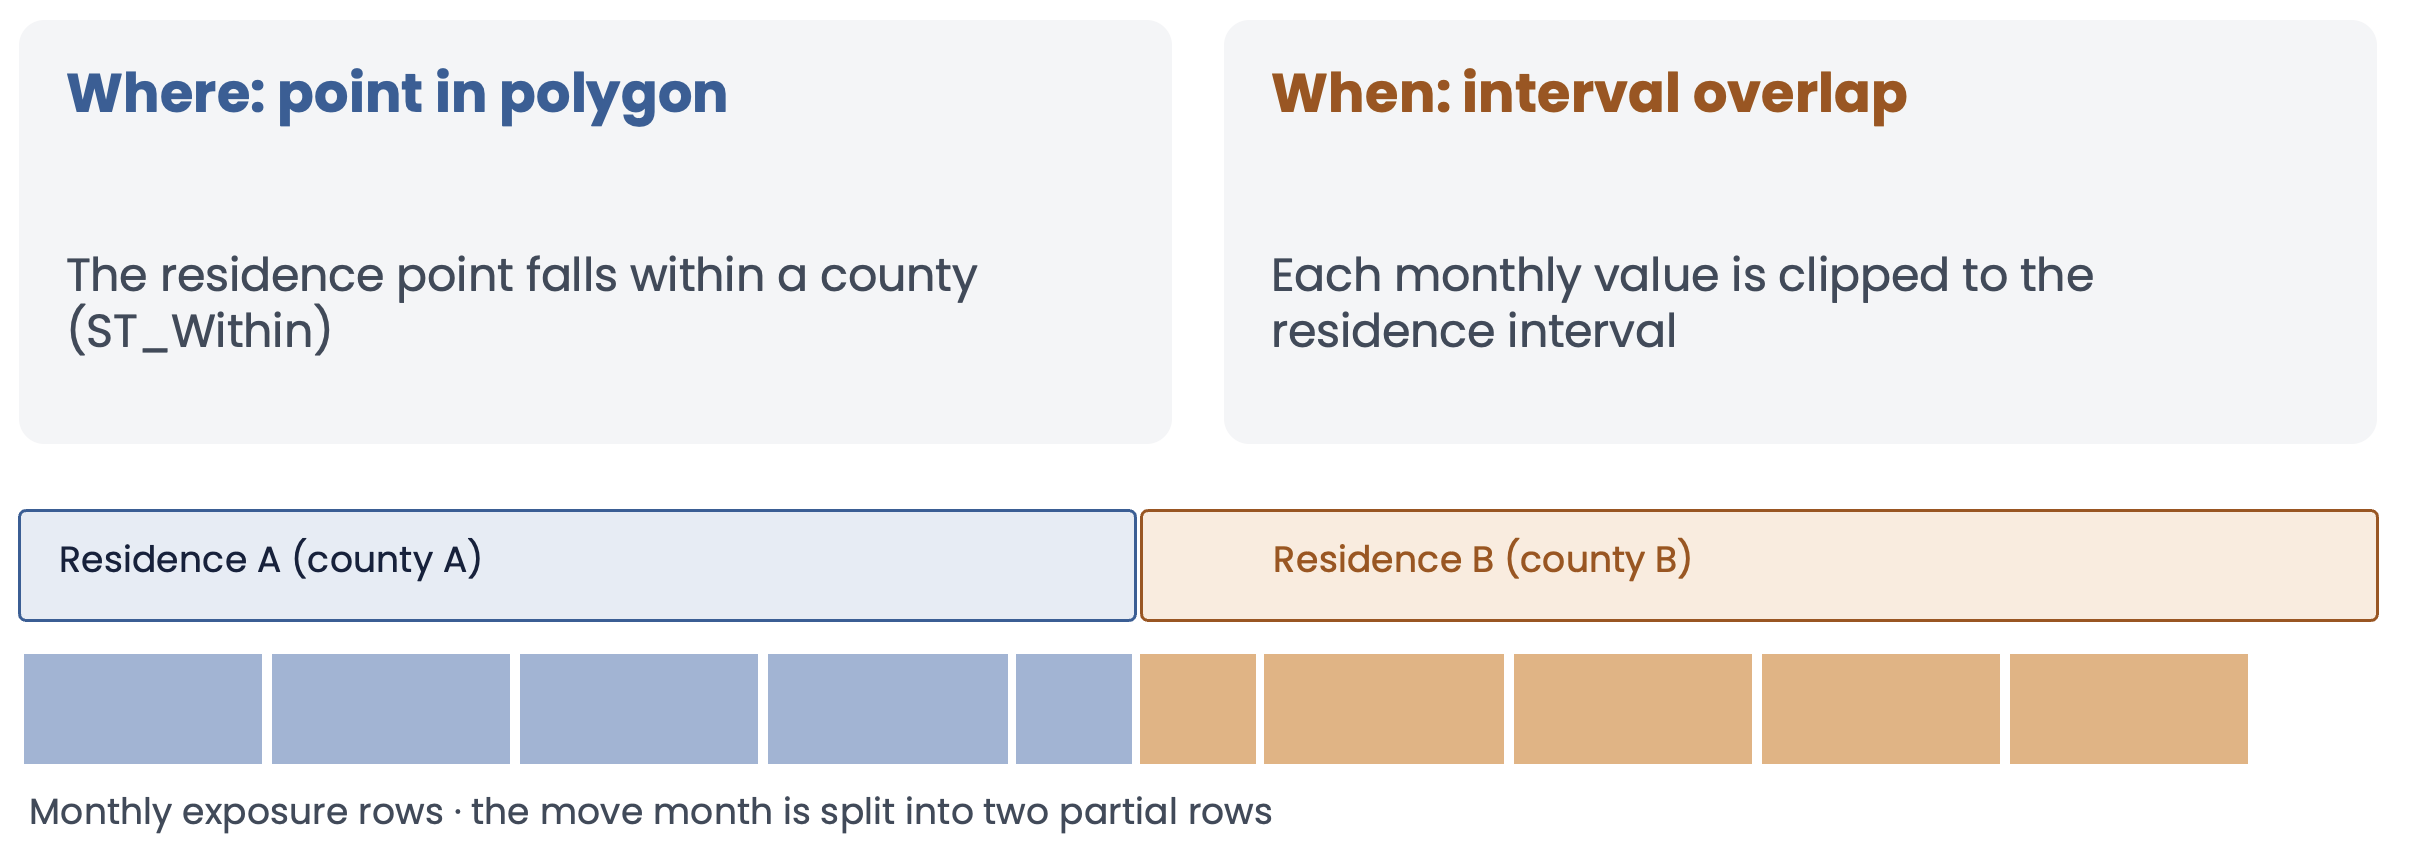
The join assigns each value in two moves: where (the
residence point falls within a county polygon, ST_Within)
and when (each monthly value is clipped to the
residence interval, so a move month is split into two partial rows).
Steps
All SQL runs in the gaia-db container:
docker compose exec gaia-db psql -U postgres -d gaiacore
(or use PGAdmin).
Deploy the stack and load the persons. Start the pinned containers and confirm the health checks pass (see Get Started). Download
synthetic_omop_gis.sql.gz(and the fallback fileexternal_exposure_fallback.csv.gzused at the end of this exercise) from thesyntheticDataGIS/datafolder, or get them from the faculty, and copy both into thevolumes/tempfolder of yourgaiaDockercheckout: the stack mounts that folder inside the database container as/temp. The folder is not in the repository; Docker creates it the first time the stack starts, so copy the files in after the stack is up (on Linux the folder belongs to root, so usesudo cp). Then restore the synthetic dataset by running the unzip inside the container. The command is the same in PowerShell, Terminal and bash, and nothing is unzipped on your computer:docker compose exec gaia-db sh -c "gunzip -c /temp/synthetic_omop_gis.sql.gz | psql -U postgres -d gaiacore"Run it once: running it again prints “already exists” errors and loads every row twice. This creates the
omopgisanddemoschemas next to Gaia’sbackboneandworkingschemas. Check thatomopgis.personhas 10,000 rows andomopgis.external_exposureis empty.Ingest the source datasets. The county boundaries must be ingested before the PM2.5 dataset and the SES index, which are joined to them. Each call downloads the data and loads it into PostGIS, which takes several minutes (about 1.2 GB in total; the faculty can provide a pre-staged volume if bandwidth is limited). The catalog entry that drives ingestion is the metadata record from Exercise 1 (your own, or the fallback provided).
SELECT * FROM backbone.ingest_datasource('us_2023_county_tl');
SELECT * FROM backbone.ingest_datasource('us_2014_2019_monthly_pm25_by_county_cdc');
Inspect what was registered (
attr_index.variable_source_idlinks each loaded variable to itsvariable_sourcerow, and that id becomesexposure_source_value):SELECT * FROM backbone.data_source;,backbone.variable_source,backbone.geom_index, andbackbone.attr_index. The PM2.5 dataset has four variables (max, median, mean, population-weighted mean). Which one does your Exercise 1 requirement call for?The third source, the county SES index, is simulated, but it is ingested exactly like the other two. Its entry is part of gaiaCatalog (
synthetic_county_ses: JSON-LD record, ETL metadata, and the_osgeo.shand_postgis.shscripts, the same layout as the CDC PM2.5 entry), and its source file (county_ses.csv, two columns:geoid,ses_index) is downloaded from the tutorial repository. Ingest it after the counties, which its polygons come from:SELECT * FROM backbone.ingest_datasource('synthetic_county_ses');Check
backbone.attr_index: there is now anses_indexvariable next to the four PM2.5 variables, with the SES concept from the record.Load the persons’ locations into Gaia. Gaia joins exposures to
working.locationandworking.location_history, so copy the synthetic residences there and validate them:INSERT INTO working.location (location_id, address_1, address_2, city, state, zip, county, location_source_value, country_concept_id, country_source_value, latitude, longitude, geom) SELECT location_id, address_1, address_2, city, state, zip, county, location_source_value, country_concept_id, country_source_value, latitude, longitude, ST_SetSRID(ST_MakePoint(longitude, latitude), 4326) FROM omopgis.location; INSERT INTO working.location_history (location_id, relationship_type_concept_id, domain_id, entity_id, start_date, end_date) SELECT location_id, relationship_type_concept_id, domain_id, entity_id, start_date, end_date FROM omopgis.location_history; SELECT * FROM working.location_statistics(); SELECT * FROM working.validate_location_data();Some persons have two
location_historyrows. Why? (Look at their dates.)Build the geometry and attribute tables, then run the spatial joins for the PM2.5 variable you chose (here the monthly mean) and for the SES index:
SELECT * FROM backbone.gdsc_load_all_variables(
    p_table_id => 'us_2014_2019_monthly_pm25_by_county_cdc',
    p_geom_label => 'name', p_variable_nodata => -999,
    p_source => 'CDC EPHTN daily county PM2.5 (EPA Downscaler), monthly means');

SELECT working.spatial_join_from_catalog('pm25_mean_pred', 'us_2014_2019_monthly_pm25_by_county_cdc',
                                         p_exposure_type_concept_id => 2052499878);  -- Air Quality Database

SELECT * FROM backbone.gdsc_load_all_variables(
    p_table_id => 'synthetic_county_ses',
    p_geom_label => 'name', p_variable_nodata => -999,
    p_source => 'Simulated county SES index (tutorial)');

SELECT working.spatial_join_from_catalog('ses_index', 'synthetic_county_ses',
                                         p_exposure_type_concept_id => 2052497765);  -- SDOH Database
The last argument sets
exposure_type_concept_id: the type of the data source (an “Exposure Type Concept”), which Gaia cannot infer. Join one variable at a time. The SES index is joined the same way: it is static over 2014-2019, so it produces one row per residence interval (not per month).working.spatial_join_all_from_catalog(...)would also join the max, median, and population-weighted variables and multiply the row count by four. Now identify the spatial assignment pattern used (point-in-polygon, nearest feature, buffer/intersection, raster extraction, or areal aggregation; look at the operator argument, at theexposure_relationship_concept_idit produced, and atexposure_relationship_source_value, which keeps the verbatim operator) and the temporal assignment pattern (interval overlap, calendar aggregation, moving window, lag, or cumulative exposure; compareattr_start_date/attr_end_datein the attribute table with the residence interval).Check the result against the answer key.
demo.expected_resultholds the expected counts:SELECT metric, value, notes FROM demo.expected_result WHERE fixture_tag = 'GLOBAL'; SELECT exposure_concept_id, count(*) AS rows_derived, count(DISTINCT person_id) AS persons FROM working.external_exposure GROUP BY 1 ORDER BY 1; SELECT rows_per_person, count(*) AS persons FROM (SELECT person_id, count(*) AS rows_per_person FROM working.external_exposure WHERE exposure_concept_id = 2052499839 GROUP BY person_id) x GROUP BY 1 ORDER BY 1;The SES index gives one row per residence interval (
n_ses_rowsin the answer key). Every person should have 72 monthly PM2.5 rows (6 years x 12 months), except movers who change county in the middle of a month, who have 73 because that month is split into two partial-month rows.QA drill.
demo.rejected_exposure_rowcontains four deliberately bad staging rows that a loader must not accept as clean data. For each, write a check and show that it flags the row:SELECT r.fixture_tag, EXISTS (SELECT 1 FROM working.external_exposure e WHERE e.exposure_concept_id = 2052499839 AND e.person_id = r.person_id AND e.location_id = r.location_id AND e.exposure_start_date = r.exposure_start_date AND e.exposure_end_date = r.exposure_end_date) AS already_loaded, r.dose_unit_source_value, r.value_as_number IS NULL AS null_value, NOT EXISTS (SELECT 1 FROM working.location_history lh WHERE lh.entity_id = r.person_id AND r.exposure_start_date <= lh.end_date AND r.exposure_end_date >= lh.start_date) AS outside_residence FROM demo.rejected_exposure_row r ORDER BY 1;Which flag catches which row (duplicate, unit mismatch, non-overlapping interval, NULL value)? What should the pipeline do with each?
Trace one row’s lineage. Pick one exposure row, for example March 2017 for the person with the
DUPLICATE_SOURCE_ROWfixture, and follow it from the exposure row to the residence interval it was clipped to, the county polygon the point fell in, the variable it came from, the source attribute row, and the raw value in the ingested table:WITH pick AS (SELECT person_id FROM demo.fixture_person WHERE fixture_tag = 'DUPLICATE_SOURCE_ROW') SELECT ee.external_exposure_id, ee.person_id, ee.exposure_start_date, ee.exposure_end_date, ROUND(ee.value_as_number::numeric, 3) AS exposure_value, lh.location_history_id, lh.start_date AS residence_start, lh.end_date AS residence_end, ee.exposure_source_value, vs.variable_source_id, vs.variable_name, src.geoid, geo.geom_name AS county, att.attr_start_date, att.attr_end_date, ROUND(att.value_as_number::numeric, 3) AS source_value, src.pm25_mean_pred ->> (att.attr_start_date || '/' || att.attr_end_date) AS raw_json_value FROM working.external_exposure ee JOIN pick USING (person_id) JOIN working.location_history lh ON lh.location_id = ee.location_id AND lh.entity_id = ee.person_id JOIN working.location loc ON loc.location_id = ee.location_id JOIN working.geom_us_2014_2019_monthly_pm25_by_county_cdc geo ON ST_Within(loc.geom, geo.geom_wgs84) JOIN working.attr_us_2014_2019_monthly_pm25_by_county_cdc att ON att.geom_record_id = geo.geom_record_id AND att.attr_start_date = ee.exposure_start_date AND att.attr_index_id = (SELECT attr_index_id FROM backbone.attr_index WHERE variable_name = 'pm25_mean_pred') JOIN backbone.attr_index ai ON ai.attr_index_id = att.attr_index_id JOIN backbone.variable_source vs ON vs.variable_source_id = ai.variable_source_id AND vs.variable_source_id::text = ee.exposure_source_value JOIN public.us_2014_2019_monthly_pm25_by_county_cdc src ON src.ogc_fid = geo.geom_record_id WHERE ee.exposure_start_date = '2017-03-01';exposure_source_valueshould equal thevariable_source_idof the variable you joined, which the join tovariable_sourceconfirms. Write two or three sentences explaining that one row: what it represents, where its value came from, and what interval it applies to. Then do the same for a row in the month a mover changes county, where the interval is shorter than a month.Move the result into the OMOP table so the next session can query it:
INSERT INTO omopgis.external_exposure (
    location_id, person_id, exposure_concept_id, exposure_start_date, exposure_start_datetime,
    exposure_end_date, exposure_end_datetime, exposure_type_concept_id,
    exposure_relationship_concept_id, exposure_source_concept_id, exposure_source_value,
    exposure_relationship_source_value, dose_unit_source_value, quantity, modifier_source_value,
    operator_concept_id, value_as_number, value_as_concept_id, unit_concept_id)
SELECT location_id, person_id, exposure_concept_id, exposure_start_date, exposure_start_datetime,
       exposure_end_date, exposure_end_datetime, exposure_type_concept_id,
       exposure_relationship_concept_id, exposure_source_concept_id, exposure_source_value,
       exposure_relationship_source_value, dose_unit_source_value, quantity, modifier_source_value,
       operator_concept_id, value_as_number, value_as_concept_id, unit_concept_id
FROM working.external_exposure
WHERE person_id > 0;
If the pipeline does not run on your machine, load
the derived exposure from external_exposure_fallback.csv.gz
instead of steps 2 to 4 and 8:
docker compose exec gaia-db psql -U postgres -d gaiacore -c "\copy omopgis.external_exposure FROM PROGRAM 'gunzip -c /temp/external_exposure_fallback.csv.gz' WITH (FORMAT csv, HEADER true)"Then run the checks in steps 5 and 6 against the OMOP tables (replace
working.external_exposure with
omopgis.external_exposure and
working.location_history with
omopgis.location_history). The lineage trace in step 7
needs the Gaia geometry and attribute tables, so ask a faculty member to
run it for you or to share a screen.
Deliverable
One row’s lineage, traced end to end (dataset variable and geometry → residence interval → derived exposure row), with a short written explanation, plus the QA drill results (which check catches which bad row).
Check Your Work
Bridge to Session 3: a computed value is not interoperable until its semantics are standardized. That’s what the OMOP integration does next.
Previous: Exercise 1 | Next: Exercise 3